Building a Career as a Web3 Blockchain Infrastructure Engineer Roadmap and Systems Architecture
A technical roadmap and systems architecture guide for blockchain infrastructure engineers, covering RPC node orchestration, validator sentry architecture, NVMe storage optimization, indexer pipelines, and career progression.
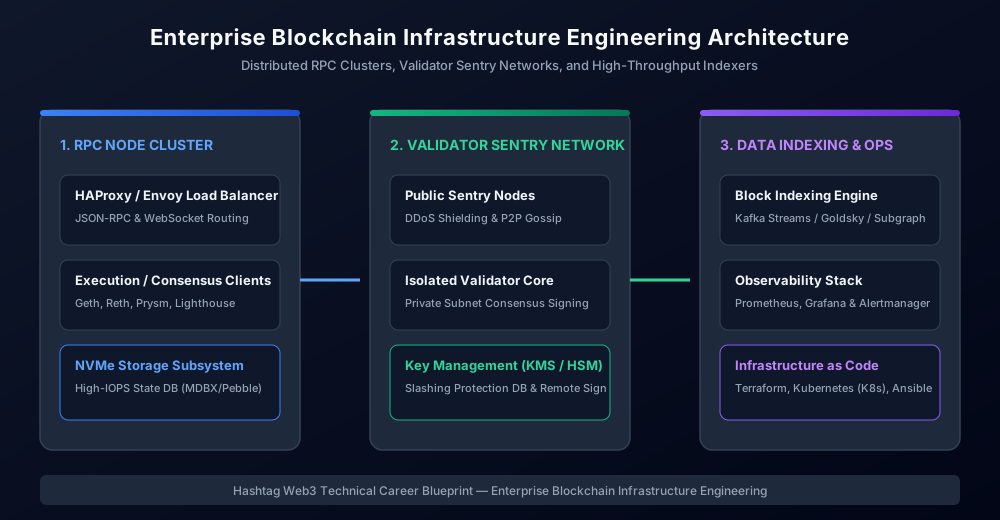
Blockchain Infrastructure Engineering is one of the most critical and high-demand disciplines in the Web3 ecosystem. While smart contract developers write decentralized application logic, infrastructure engineers build and maintain the low-level systems that keep decentralized networks online: high-availability RPC node clusters, validator sentry nodes, block indexers, MEV relays, and distributed storage networks.
Operating blockchain infrastructure requires a hybrid skill set combining cloud-native DevOps, low-level Linux kernel tuning, high-performance NVMe storage management, peer-to-peer (P2P) networking, and cryptographic key security. This comprehensive technical guide presents a complete roadmap for building a career as a Web3 Blockchain Infrastructure Engineer, detailing architecture patterns, operational playbooks, and career progression.
1. Core Technical Foundations of Blockchain Infrastructure
Blockchain nodes are stateful applications with intensive hardware resource profiles. Unlike traditional stateless microservices, blockchain nodes maintain massive, append-only state databases, process concurrent cryptographic signatures, and execute P2P gossip protocol messages across decentralized networks.
The Blockchain Node Taxonomy
Understanding node configurations is fundamental to infrastructure design across Layer 1 and Layer 2 systems:
- Full Nodes: Maintain the current world state and validate all blocks and transactions against consensus rules. Full nodes prune historical state trie data (e.g., intermediate EVM account states) to conserve storage space.
- Archive Nodes: Retain every historical state transition since the genesis block. In Ethereum, an archive node exceeds 14 TB of storage (using flat DB layouts), making storage optimization a primary engineering challenge.
- Validator / Staking Nodes: Participate directly in consensus block production and voting. Validators require strict zero-downtime execution and secure Key Management Systems (KMS) to prevent double-signing penalties (slashing).
- RPC (Remote Procedure Call) Gateways: Expose public or private JSON-RPC endpoints to frontend dApps, wallets, and indexers. RPC nodes handle read/write query load balancing and state caching.
┌─────────────────────────────────────────────────────────────────┐
│                    RPC NODE INFRASTRUCTURE                      │
└────────────────────────────────┬────────────────────────────────┘
                                 │
         ┌───────────────────────┴───────────────────────┐
         ▼                                               ▼
┌──────────────────────────────┐        ┌──────────────────────────────┐
│     Execution Client         │        │      Consensus Client        │
│   (Reth / Geth / Nethermind) │◄──────►│  (Prysm / Lighthouse / Teku) │
└────────┬─────────────────────┘        └────────┬─────────────────────┘
         │ Engine API (JWT Auth)                 │ Beacon Chain API
         ▼                                       ▼
┌──────────────────────────────┐        ┌──────────────────────────────┐
│  State DB (MDBX / Pebble)    │        │  P2P Gossip Network (Libp2p) │
└──────────────────────────────┘        └──────────────────────────────┘
2. RPC Node Cluster Architecture and Load Balancing
Serving millions of JSON-RPC requests daily (e.g., eth_call, eth_getLogs, eth_sendRawTransaction) requires a distributed, fault-tolerant cluster design capable of handling high throughput without incurring data inconsistency.
Load Balancer and Routing Configuration
In front of execution clients, engineers deploy HAProxy, NGINX, or Envoy proxy layers configured with custom health-checking logic:
- Block Height Sync Tracking: The load balancer queries
eth_blockNumberevery 2 seconds. Any node lagging more than 2 blocks behind the network tip is automatically removed from active routing pools. - Request Splitting: Read-heavy queries (
eth_call,eth_getStorageAt) are routed to auto-scaling read replicas, while transaction submissions (eth_sendRawTransaction) are broadcast concurrently across multiple execution clients to maximize transaction propagation speed across P2P mempools.
# NGINX Upstream Load Balancer Configuration for Ethereum RPC Cluster
http {
    upstream rpc_backend {
        zone rpc_service 64k;
        server rpc-node-01.internal:8545 max_fails=2 fail_timeout=5s;
        server rpc-node-02.internal:8545 max_fails=2 fail_timeout=5s;
        server rpc-node-03.internal:8545 backup;
    }

    server {
        listen 8080;
        server_name rpc.hashtagweb3.com;

        location / {
            proxy_pass http://rpc_backend;
            proxy_http_version 1.1;
            proxy_set_header Upgrade $http_upgrade;
            proxy_set_header Connection "upgrade";
            proxy_set_header Host $host;
            proxy_set_header X-Real-IP $remote_addr;
        }
    }
}
3. Validator Sentry Architecture and Slashing Protection
For proof-of-stake networks (Ethereum, Solana, Cosmos, Avalanche), securing validator nodes against Distributed Denial of Service (DDoS) attacks and key compromise is the top infrastructure priority.
Sentry Node Architecture Pattern
To isolate validator signing keys from the public internet, engineers implement the Sentry Architecture:
[Public P2P Network] ──► [Public Sentry Node A] ──┐
                                                 │ (Private WireGuard VPN)
[Public P2P Network] ──► [Public Sentry Node B] ──┼──► [Protected Validator Core Node]
                                                 │      (Hardware Security Module)
[Public P2P Network] ──► [Public Sentry Node C] ──┘
- Public Sentry Nodes: Deployed in public subnets with open P2P ports (e.g., port 30303). Sentries handle external P2P gossip traffic and shield the validator's IP address.
- Private Validator Core: Deployed in an isolated, private subnet with zero public ingress. The validator connects exclusively to its sentry nodes via encrypted WireGuard or IPsec VPN tunnels.
- Remote Signer & HSM: Signing keys reside in a dedicated Key Management System (such as Web3Signer or AWS KMS). The validator node sends signing requests over an internal gRPC connection to the remote signer, which validates slashing protection rules before signing block proposals.
4. Storage Subsystem and OS Kernel Tuning
Blockchain nodes perform heavy, randomized I/O operations (IOPS) on state databases (such as MDBX, LevelDB, or PebbleDB). Storage bottlenecks lead to dropped P2P peers and lost block synchronization.
Hardware and File System Selection
- NVMe Solid-State Drives: Enterprise PCIe 4.0/5.0 NVMe SSDs with sustained random read/write capabilities exceeding 100,000 IOPS are mandatory for production nodes.
- File System Configuration: ZFS or XFS configured with
noatimeflags to reduce unnecessary disk write operations.
Linux Kernel Optimization (sysctl.conf)
Engineers optimize Linux kernel parameters to manage network buffers and memory allocations for high-throughput node operation:
# /etc/sysctl.d/99-blockchain-node.conf

# Increase max socket receive and send buffer sizes for P2P gossip
net.core.rmem_max = 67108864
net.core.wmem_max = 67108864
net.core.rmem_default = 33554432
net.core.wmem_default = 33554432

# Increase max open file descriptors for heavy DB operations
fs.file-max = 2097152

# Tune memory virtual memory dirty ratios for persistent disk writes
vm.dirty_background_ratio = 5
vm.dirty_ratio = 10
vm.swappiness = 10
5. Infrastructure as Code (IaC) and Kubernetes Orchestration
Modern blockchain operations manage node clusters using Infrastructure as Code (IaC) tools like Terraform and Ansible, coupled with Kubernetes (K8s) orchestration.
Kubernetes StatefulSets for Blockchain Nodes
Because blockchain nodes maintain state, they are deployed using Kubernetes StatefulSet resources coupled with PersistentVolumeClaims backed by high-performance cloud storage (e.g., AWS io2 or local NVMe storage classes).
apiVersion: apps/v1
kind: StatefulSet
metadata:
  name: reth-execution-node
  namespace: blockchain-infra
spec:
  serviceName: "reth-internal"
  replicas: 3
  selector:
    matchLabels:
      app: reth-node
  template:
    metadata:
      labels:
        app: reth-node
    spec:
      containers:
      - name: reth
        image: ghcr.io/paradigmxyz/reth:v1.0.0
        args:
          - "node"
          - "--http"
          - "--http.addr=0.0.0.0"
          - "--http.api=eth,net,trace,web3"
          - "--authrpc.addr=0.0.0.0"
          - "--authrpc.jwtsecret=/var/run/jwt/jwt.hex"
        ports:
          - containerPort: 8545
            name: rpc
          - containerPort: 30303
            name: p2p
        resources:
          requests:
            memory: "32Gi"
            cpu: "8"
          limits:
            memory: "64Gi"
            cpu: "16"
        volumeMounts:
          - name: reth-data
            mountPath: /root/.local/share/reth
  volumeClaimTemplates:
  - metadata:
      name: reth-data
    spec:
      accessModes: [ "ReadWriteOnce" ]
      storageClassName: "gp3-nvme-high-iops"
      resources:
        requests:
          storage: 3Ti
6. Observability, Monitoring, and Alerting Stacks
Maintaining 99.99% uptime for blockchain infrastructure requires real-time observability stacks built around Prometheus, Grafana, and Alertmanager.
Key Monitoring Metrics
- Sync Distance (
chain_head_block - node_current_block): Alert if sync distance > 2 blocks. - P2P Peer Count (
p2p_peer_count): Alert if peer count drops below 15 active connections. - Disk I/O Utilization (
rate(node_disk_written_bytes_total[5m])): Track IOPS saturation and disk space exhaustion warnings at 80% capacity. - Consensus Slashing Alarms: Real-time alerts for missed attestation epochs or double-proposal attempts.
┌─────────────────────────────────────────────────────────────────┐
│                 BLOCKCHAIN OBSERVABILITY STACK                  │
└────────────────────────────────┬────────────────────────────────┘
                                 │
         ┌───────────────────────┼───────────────────────┐
         ▼                       ▼                       ▼
┌─────────────────┐     ┌─────────────────┐     ┌─────────────────┐
│ Node Metrics    │     │ Prometheus      │     │ Grafana         │
│ (Prometheus Format)   │ Push/Pull Model │     │ Dashboards      │
└────────┬────────┘     └────────┬────────┘     └────────┬────────┘
         │                       │                       │
         └───────────────────────┼───────────────────────┘
                                 ▼
                        ┌─────────────────┐
                        │ Alertmanager    │
                        │ (PagerDuty/Slack│
                        └─────────────────┘
7. High-Throughput Indexing Pipelines
Front-end applications and analytics platforms cannot rely directly on raw JSON-RPC nodes for complex queries. Infrastructure engineers construct indexing pipelines that ingest, parse, and store decoded blockchain event data in relational databases or data warehouses.
Real-Time Pipeline Architecture
- Block Stream Engine: Ingests raw blocks via WebSocket subscriptions or Execution Client Engine APIs.
- Stream Processor (Kafka / Flink): Decodes raw ABI event logs into structured schema formats (e.g., ERC-20
Transferevents). - Storage Engine: Writes structured records into PostgreSQL, ClickHouse, or BigQuery for fast SQL analytics.
8. Layer 2 Rollup Infrastructure and Sequencer Nodes
As Ethereum scales via Layer 2 rollups (Arbitrum, Optimism, Base, zkSync), infrastructure engineers must master rollup-specific infrastructure components.
1. Sequencer Node Architecture
Rollup sequencers ingest user transactions, order them, and produce L2 blocks within milliseconds:
- Centralized Sequencer Stack: Manages rapid transaction batching and posts state commitments to L1 Ethereum contracts.
- Decentralized Sequencers (Shared Sequencers): Implement consensus protocols (like Espresso or Astria) across distributed sequencer sets to prevent transaction censorship.
2. Batchers and Provers
- Batcher Services: Compress L2 transaction batches and submit calldata or EIP-4844 Blob data (
blob_data) to L1 Ethereum. - ZK Provers (SNARK/STARK Generation): Require high-performance GPU/FPGA clusters to generate cryptographic validity proofs for Zero-Knowledge rollups.
9. MEV Relay Infrastructure and Block Building
Maximal Extractable Value (MEV) has transformed transaction supply chains. Infrastructure engineers manage MEV-Boost relays that connect validators with specialized block builders:
[Searchers (Bots)] ──► [Block Builders] ──► [MEV-Boost Relay] ──► [Validator Node]
Relay nodes must run on low-latency infrastructure with sub-100ms processing constraints to ensure builders can deliver profitable payload blocks to validators before slot proposal deadlines.
10. Security Engineering and Private Key Management Systems
Securing signing keys for validators, cross-chain bridges, and automated protocol vaults requires dedicated cryptographic key security frameworks.
Key Security Taxonomies
- Hot Keys (Automated Signing): Used by sequencers and automated keepers. Protected using Hardware Security Modules (HSM) or cloud KMS with strict rate-limiting policies.
- Warm Keys (Multi-Sig Wallets): Used for protocol operational treasuries (Safe / Gnosis Safe). Require multiple signatures from distinct hardware devices (YubiKeys / Ledgers).
- Cold Keys (Offline Storage): Master validator withdrawal keys stored offline in air-gapped physical vaults.
11. Multi-Region Disaster Recovery and Chaos Engineering
Operating enterprise-grade blockchain infrastructure requires robust disaster recovery (DR) protocols and proactive fault injection testing.
1. Multi-Region Failover Architecture
- Active-Active RPC Deployments: Distribute RPC node clusters across US-East, Europe-Central, and Asia-Pacific regions to minimize round-trip latency for global users.
- Cross-Region State Sync: Use snapshot storage buckets (AWS S3 / Google Cloud Storage) to sync new node replicas within hours rather than waiting days for P2P sync.
2. Chaos Engineering Playbooks
Engineers regularly simulate infrastructure failures using Chaos Mesh or Litmus Chaos:
- Network Partition Simulation: Simulating P2P disconnection between sentries and validator core nodes to verify failover routing.
- Disk I/O Latency Injection: Verifying that execution clients handle transient disk throttling without crashing.
12. Bare-Metal vs Cloud Infrastructure Cost Analysis
Deploying blockchain nodes in cloud environments (AWS, GCP) vs bare-metal hardware providers (Hetzner, Equinix, OVH) involves significant trade-offs between speed of provisioning and monthly operational expenditure (OpEx).
Cost Comparison Framework
                          MONTHLY INFRASTRUCTURE COST

 Venue                    Storage (3TB NVMe)    Compute (64GB RAM)   Bandwidth (10TB)
──────────────────────────────────────────────────────────────────────────────────────────
 AWS (EBS gp3 / EC2)      ~$360 / mo            ~$240 / mo           ~$900 / mo
 Bare-Metal (Dedicated)   Included in Server    ~$120 / mo total     Included (Unmetered)
While cloud providers offer managed elasticity and instant snapshots, large-scale node operators frequently run bare-metal or hybrid deployments to reduce bandwidth and storage egress fees by up to 70%.
13. Decentralized Physical Infrastructure Networks (DePIN) and Storage Protocols
Infrastructure engineering extends beyond traditional RPC hosting into Decentralized Physical Infrastructure Networks (DePIN). Protocols like Arweave, Filecoin, and Akash allow engineers to construct fully decentralized hosting pipelines:
- Arweave & Filecoin: Used for permanent state archiving, historical block snapshot storage, and NFT metadata hosting.
- Akash Network: Open-source cloud marketplace enabling containerized workloads to be deployed across independent hardware providers.
14. Automated On-Call Incident Response Playbook
When maintaining production node clusters, infrastructure engineers establish automated incident response playbooks for common operational failures.
Incident 1: Execution Client Memory Leak (OOM Kill)
- Automated Trigger: Prometheus
container_memory_working_set_bytesbreaches 90% threshold. - Immediate Remediation: Pod restarts via Kubernetes
livenessProbe. - Root Cause Analysis: Inspect client heap dumps and update memory ceiling arguments (
--memory-limit).
Incident 2: Consensus Client State Reorg / Fork Branching
- Automated Trigger: Beacon client reports
beacon_head_slotmismatch relative to peers. - Remediation: Resync consensus client state from trusted checkpoint sync endpoint (
--checkpoint-sync-url).
15. Cross-Chain Bridge Validator Infrastructure
Cross-chain messaging protocols (such as LayerZero, Chainlink CCIP, Axelar, and Wormhole) rely on distributed validator networks to relay cryptographic proofs across heterogeneous blockchains. Infrastructure engineers build multi-chain validator stacks that maintain concurrent RPC connections across 20+ distinct Layer 1 and Layer 2 chains:
- Multi-Chain Node Bundling: Running lightweight RPC clients across non-EVM chains (Solana, Aptos, Sui, Cosmos) alongside EVM execution clients.
- Relayer Attestation Security: Ensuring that cross-chain proof signatures are generated within isolated enclaves (AWS Nitro Enclaves or Intel SGX) to prevent cross-chain relay exploitation.
16. Career Roadmap and Progression for Blockchain Infrastructure Engineers
Building a career in blockchain infrastructure requires mastering cloud technologies, networking, and blockchain-specific protocol design.
                          CAREER PROGRESSION ROADMAP

 [Junior DevOps Engineer]
           │
           ▼
 [Blockchain Node Engineer] ──► (Master RPC Clustering, Client Management)
           │
           ▼
 [Senior Infra Architect]   ──► (Master Validator Security, KMS, Indexing)
           │
           ▼
 [Head of Infrastructure]   ──► (Global Cloud Strategy, Multi-Region Scale)
Core Skills Matrix
| Skill Domain | Foundational Competencies | Advanced / Enterprise Competencies |
|---|---|---|
| Linux & Cloud Systems | Bash, Systemd, Linux I/O, AWS/GCP | Kernel tuning (sysctl), BPF/eBPF profiling, bare-metal hardware |
| Containers & IaC | Docker, Docker Compose, Basic K8s | Kubernetes Operators, Terraform, Helm, ArgoCD GitOps |
| Blockchain Nodes | Geth, Besu, Solana CLI, Cosmos Gaia | Client optimization, Reth, Erigon DB architecture, MEV-Boost |
| Security & Key Mgt | SSH keys, Firewalls (UFW), TLS | HSM integration, Web3Signer, Slashing protection DBs |
| P2P Networking | Port forwarding, DNS, VPC routing | Libp2p tuning, BGP routing, WireGuard VPN mesh networks |
17. Interview Preparation and Technical Assessment Playbook
Candidates interviewing for Senior Blockchain Infrastructure roles are routinely tested on scenario-based architectural challenges.
Scenario: Resolving RPC Node Synchronization Latency
Interview Question: "Your Ethereum RPC cluster nodes are falling 20 blocks behind the tip of the network during high-volatility events. How do you diagnose and resolve this performance issue?"
Structured Engineering Answer:
- Log and Metric Inspection: Check CPU usage, memory pressure, and disk I/O metrics via Grafana. Verify whether the bottleneck is CPU execution saturation or storage IOPS throttling.
- P2P Peer Health: Query node peer counts (
net_peerCount). If peer count is low (<10), update bootstrap nodes and verify firewall rules for P2P TCP/UDP ports. - State Database Optimization: Switch from legacy execution clients to next-generation high-performance clients (such as Reth or Erigon) optimized for parallel state execution and MDBX storage backends.
- Hardware Storage Upgrade: Migrate node persistent volumes from network-attached block storage (AWS EBS
gp3) to local NVMe SSD storage arrays configured in RAID 0 for maximum write throughput.
Summary and Key Takeaways
Blockchain Infrastructure Engineering bridges cloud-native DevOps with decentralized protocol security. As decentralized networks scale to process tens of thousands of transactions per second across Layer 1 chains and Layer 2 rollups, the demand for skilled engineers who can deploy resilient, secure, and performant node architectures will continue to accelerate.
Mastering node operations, validator sentry design, storage optimization, and automated monitoring provides a clear foundation for a high-impact career building the backbone of the Web3 economy.