
Becoming a Web3 Decentralized Storage Expert
A comprehensive career and technical roadmap for becoming a Web3 decentralized storage expert, examining IPFS, Arweave, Filecoin, erasure coding, and infrastructure engineering.
Becoming a Web3 Decentralized Storage Expert
Decentralized storage is not one service or one durability guarantee. It is a set of systems that separate a file's identity from a single server and distribute storage, retrieval, or verification across participants. A useful design starts by deciding what must be immutable, who may read it, how long it must remain retrievable, and who will verify that it is still available.
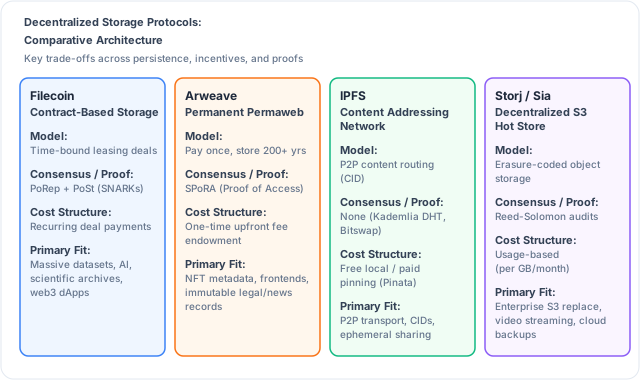
The four systems most often grouped together solve different parts of that problem. IPFS identifies and retrieves content by hash. Filecoin adds storage deals and cryptographic proofs to a decentralized storage market. Arweave records data in a network designed for long-term retention after an upfront payment. Storj provides encrypted object storage by splitting data across independent storage nodes. None removes the need for application-level backup, access control, monitoring, or incident response.
Content addressing
A location address tells a client where to ask for data, such as https://storage.example/records/42.json. The operator of that hostname can change the response, remove it, or make the host unavailable. A content address identifies a particular sequence of bytes. In IPFS, that identifier is a Content Identifier, or CID.
The CID specification defines a CID as a self-describing identifier. It contains a version, a content codec, and a multihash. The multihash records the hash function and digest, so a client can verify retrieved bytes against the identifier it requested. Changing the bytes produces a different hash and therefore a different CID.
That verification property does not say that anyone is storing the bytes. A CID can remain valid even when no reachable peer has the content. Treat content addressing as an integrity mechanism and a naming system, not as a retention policy.
IPFS typically represents a file through UnixFS. UnixFS splits data into blocks and links them in a Merkle directed acyclic graph. The root CID commits to the graph, while links identify child blocks. A client can verify each retrieved block and the links that connect it to the root. This structure supports large files and directories without requiring a single object to contain all data.
CID version matters in web integrations. CIDv0 and CIDv1 have different encodings and constraints. CIDv1 in base32 works in subdomain gateway URLs, such as https://<cid>.ipfs.gateway.example, where browser origin isolation is useful. Store CIDs as opaque strings. Do not assume a fixed prefix, hash algorithm, or length.
Availability and retrieval
An IPFS node that has a block can announce itself as a provider. Clients discover providers through routing systems such as the Kademlia DHT, then request blocks using protocols such as Bitswap. Discovery can be slow or fail when providers are offline, not connected to the public network, or have stopped advertising the content.
Pinning addresses the most common availability mistake. A pin tells an IPFS node to retain a block and its linked content rather than allowing local garbage collection. The IPFS pinning documentation is explicit that a pin affects the node or pinning service holding it. It does not create a network-wide replication guarantee. For important content, use more than one independently operated pinning or storage target and verify each copy after upload.
HTTP gateways make IPFS content accessible to browsers and applications that do not run IPFS nodes. A gateway is still an operator-controlled service. The IPFS gateway guide recommends using a dedicated gateway for production applications and describes the security differences between path, subdomain, and DNSLink gateways. A gateway timeout means that gateway could not serve the content at that moment. It does not establish whether the content has been lost.
Build retrieval as a monitored path. Record the root CID, content type, size, upload time, and the destinations that accepted the data. Regularly fetch the content through each intended route, recompute the hash or validate the CID, and alert on failures. Keep a conventional backup when recovery time or legal retention requirements are strict. A distributed storage protocol is not a substitute for a tested restore procedure.
IPFS and Filecoin
IPFS is a peer-to-peer content network. It gives applications a way to exchange and verify addressed blocks, but it does not pay nodes to keep a particular CID. It fits public assets, software artifacts, NFT metadata, and datasets when the publisher has a separate plan for replication or pinning.
Filecoin extends this model with storage providers, on-chain deals, and proofs. According to the Filecoin documentation, a client proposes a deal to a storage provider. The provider seals the data, and the network verifies continued storage with Proof of Spacetime. A deal has a defined term. It is not permanent, and applications must track its expiration and arrange renewal or a new deal.
The distinction changes an integration design. Use IPFS when a CID and retrieval from multiple peers are the main requirements. Add Filecoin when the application needs a verifiable, time-bounded storage commitment. Do not assume that an IPFS pin is automatically a Filecoin deal or that a Filecoin deal automatically supplies a fast public HTTP retrieval path. Confirm what a chosen provider offers for ingestion, retrieval, replication, and deal renewal.
Filecoin's proofs show that a provider committed capacity to sealed data over time. They do not validate that an application used the correct encryption key, recorded correct metadata, or preserved every off-chain index needed to locate the data. Keep the mapping between application records and piece or deal identifiers in a database that is backed up and access-controlled.
Arweave
Arweave takes a different economic approach. Its protocol overview describes a blockweave that links blocks to prior data and uses Succinct Proofs of Random Access, or SPoRA. Storage nodes are incentivized to retain historical data because block production requires access to a randomly selected recall range.
Users pay an upfront fee to submit data. Arweave describes the resulting storage endowment in its permaweb documentation. That is a protocol design claim, not a service-level agreement for a particular application's records. A team with contractual retention duties should define its own copies, integrity checks, and recovery procedures instead of treating any network's economic model as a legal guarantee.
Arweave transactions can carry tags that help applications classify and query content. Tags are public metadata. Do not place user identifiers, access tokens, plaintext filenames, or other sensitive information in them. Before selecting Arweave, decide whether data must ever be deleted or corrected. Immutable public storage is a poor fit for personal data that may be subject to erasure, rectification, or access restrictions.
Storj and erasure coding
Storj exposes an object-storage interface while distributing encrypted pieces across storage nodes. Its security documentation describes client-side encryption and erasure coding. An uploaded object is encrypted before pieces are distributed. The system can reconstruct an object from a threshold number of pieces, so some node failures do not make the object unavailable.
Erasure coding is different from full replication. Replication stores several complete copies. Erasure coding divides encoded data into pieces and requires a threshold to reconstruct the original. The choice trades extra CPU work and coordination for lower storage overhead than keeping many complete copies. It is useful for object storage where applications need an S3-compatible workflow and availability across independent operators.
Client-side encryption only protects data when key management is sound. The storage provider cannot recover a lost encryption key, and a leaked client key defeats the confidentiality benefit. Use a managed key service or envelope encryption scheme appropriate to the threat model. Store key identifiers and rotation state separately from the encrypted object, and test recovery with a non-production key before relying on the design.
Encryption and metadata
Content addressing can expose equality. If two people add identical unencrypted bytes to a content-addressed system, the resulting identifier can be the same. That can reveal that a known public file is present. Encrypt data before generating a CID when the content itself is sensitive.
Encryption changes deduplication and verification behavior. Randomized encryption produces different ciphertext for the same plaintext, so it normally produces different CIDs. That is often the safer default for private records. Deterministic encryption can support equality checks but needs a careful security review because it reveals repeated plaintexts.
Separate encrypted content from metadata that grants access to it. A practical record can contain a CID or object key, an encryption algorithm, a key identifier, content type, byte length, and a version. Avoid putting secrets in URLs, transaction tags, logs, or public smart-contract state. A CID proves the identity of ciphertext, not the identity or authorization of the person who uploaded it.
For mutable application records, publish a new immutable object for each version and keep a signed, access-controlled pointer to the current version. The pointer may live in a database, registry contract, or signed document depending on the application. The design must define who can update it, how conflicts are resolved, and how clients verify the pointer's signature.
Integration decisions
Choose the storage path from the data requirement rather than protocol branding.
- Use IPFS plus independent pins for public, immutable assets where a CID is the application reference and fast gateway access matters.
- Add a Filecoin deal for data that needs a verifiable storage commitment for a specified term. Monitor deal state and renew before expiry.
- Use Arweave only for content that is suitable for public, long-lived immutability and does not require deletion.
- Use Storj for encrypted object storage when an S3-compatible API and erasure-coded distribution fit the application.
- Keep at least one restore-tested copy outside the selected network for data with a defined recovery objective.
For a web application, upload first, wait for the storage destination's success response, then verify a read of the stored bytes before publishing the reference. Persist the reference and encryption metadata in a transactional application record. If an upload succeeds in one destination and fails in another, mark the record incomplete and retry idempotently. Do not show a CID to users as proof of availability until the planned replicas or deals have been confirmed.
Set explicit limits for file size, upload duration, retry count, and retrieval time. Validate MIME types and byte limits before upload. Stream large uploads rather than loading them entirely into memory. Log destination status and non-sensitive identifiers, but never log private keys, decrypted payloads, or presigned URLs.
Operational ownership remains necessary after integration. Track billing or token balances, provider account access, node health, gateway error rates, pin status, Filecoin deal end dates, and key rotation. Test a retrieval outage by disabling the preferred gateway or storage provider in a staging environment. The result should show whether the application can use a secondary route, whether CID verification still occurs, and whether users receive an accurate error when no verified copy is available.